The last post on this project ended with a rule I had found by accident. Which glyph Anima draws in a speech bubble is decided near σ 0.8, so the embedding rows that address a glyph have to be trained there, not spread over the whole noise schedule the way the default timestep sampler does it. That rule got single kana working. It was also, as it turned out, the wrong band for nearly everything else I was training, and I didn't find that out by training. I found it by asking the frozen model directly, before touching a weight, where in σ a caption can still change what it draws.
That measurement is what this post is about. The method fits in a sentence: before you train a new token into a frozen diffusion model, measure where in σ its caption has leverage on the model's prediction, and train there. The rest is what the measurement said for Japanese text in Anima, where it was right, where it was wrong, and the rule that came out of it. The pack it produced shipped today, so the end of the post is the release.
A probe that needs no training
Take a scene with a text box and render glyph B into it. Noise the image to σ and denoise it one step under two captions: one that says B, and one that says A, where A is another glyph of the same length. Each gives a one-step estimate of the clean image. Project both estimates, inside the text box, onto the line from the B render to the A render, and take the difference. If the caption has no say at this σ, both estimates sit on B and the number is 0. If the caption decides the glyph, the A-captioned estimate sits on A and the number is 1. I call the number the caption's leverage. A sweep over six σ values on 48 pairs runs in about 90 seconds, and nothing is trained.
It needs a reference. A trained row can only ever be as good as text the model already reads natively, so the ceiling is English: Latin letters, and nonsense words like RENO and PANUBU that the base model renders in the right order most of the time. Everything below is English on the base model unless it says otherwise.
Here is the first sweep, a single letter at bubble size, next to the trained kana rows from the previous post and the untouched rows they started from:
Three things in one table. Below σ 0.7 the caption has no leverage on a single glyph, for native text and trained rows alike: at 0.5 the estimate moves 1% of the way, at 0.6 5%. At 0.8 native text holds about a fifth of the estimate and the noisy input holds the rest, and the trained rows reach 78% of that ceiling. And the rows nobody trained have zero leverage at every σ, so whatever a row has, training put there, and it put it where the row was trained: the rows hold 0.12 at σ 0.9, above native text's 0.07, because 0.7–0.9 is the band they were trained in.
So far the previous post's rule holds, for single glyphs at this size. Then I ran the same probe on strings.
A string lives somewhere else entirely. Identity peaks at 0.6 with a quarter of the estimate, five times the single-letter number, and is dead at 0.8–0.9 where the single letter peaks. Order, whether the caption's word sequence can swap the rendered one, wakes a step earlier and peaks at 0.5. Below 0.4 the input pins everything. And the multi-glyph rows I had trained by then, two whole tables of them, read at or under 0.06 at every σ. They had been trained at 0.7–0.9, where the model gives a string nothing to do. The sentence runs that, in the previous post, had not moved a single ruler were explained by a 90-second read.
The ceiling table
If one glyph and a string of them live in different bands, the next question is what the band is keyed on. I pinned the font and the layout and swept the rendered size from 12 px to 128 px, for a single letter, a two-word string, and a letter sitting in the centre of a 3×3 grid of other letters. Peak is the σ with the most leverage; live is the range where the mean leverage stays above 0.1.
Strings above 48 px crop on a 512 canvas, hence the gaps. What the table says:
Size is the variable, and it is monotone. One grid step of σ per roughly every doubling of px, no plateau. A 128 px letter is decided at σ 0.8, a 16 px letter at 0.4. The previous post's "0.8" was never a property of kana; it was a property of 50–200 px glyphs, which is what that data happened to contain.
Ink is not. I reran the letter sweep in Light and Black weights of the same font. Light and Regular are the same font on this ruler. Black carries 1.5–1.7× the ink and moves the peak at exactly one px, 96, where Regular's own 0.7 and 0.8 were a near tie. Black at 48 px (8.1 cells² of ink) peaks at 0.6 while Regular at 64 px (8.6 cells²) peaks at 0.7: same ink, different px, different σ.
The bubble is not. A letter inside a drawn speech-bubble ellipse reads identically to a letter on a flat background, to the second decimal, at every px. A grid cell is different: the band moves up by 0.1–0.2 σ from 32 px on and the leverage halves, because the caption for the centre cell is one of nine and the eight neighbours are legible glyphs the model reads at the same σ.
Small text is not hard. I had assumed 16 px glyphs, the size text actually is on a manga page, would be the case where the caption loses. The opposite: a 12–16 px letter carries more leverage (0.36–0.41 at its peak) than a 24 px one (0.30) or a 48 px one (0.27), over a band twice as wide. What moves with px is where the band sits, not whether the caption can decide the glyph. That is the number that made me think a vocab pack could serve LoRA training on real pages, not just synthetic composites.
Count, at the ceiling, goes the wrong way. A string peaks 0.1 σ above a single letter at the same font px, at every valid size, on all three fonts. Keep that in mind, because training reversed it.
Where the ceiling was wrong
A ceiling table says where the caption can move the model. It does not say which part of that window a row needs while it is being trained, and the first training read showed the difference.
The cell was 24 cold kana rows, trained on scene composites where a single kana fills a speech bubble at about 48 px, 190 steps per row, at two bands. The table above puts a 48 px letter at 0.5–0.7, so that band should win.
The high band won on every ruler, and on the two scene rulers by far more than the spread between seeds. The misses explain it. The low band's misses are the right glyph drawn more than once: い comes out as いい, の as ののののののの. The high band's few misses are identity swaps, お for む, マ for チ. The low band teaches identity and never visits the σ where "one glyph, once" is decided. A single row has to carry its own count, and count is decided above identity.
The multi-glyph pieces, meanwhile, read the other way. On 16 rows that each address a kana-only Qwen piece of two to four glyphs, rendered at 35 px, 0.5–0.7 scored 7 of 32 on the exact ruler and 6 of 64 in scenes; 0.7–0.9 scored 1 and 1. The ceiling puts a 48 px letter and a 35 px string in the same live band, and at the ceiling the string peaks higher. In training, the single went up and the piece went down. What differs is the count: a piece's glyph count is in its token, so it can sit on the identity peak. A single row's "one glyph" has to be learned where the DiT lays text out, above 0.7.
That is the rule the shipped pack was trained under. A row's band is keyed on its glyph count: singles at 0.7–0.9, multi-glyph pieces at 0.5–0.7. Rendered px sets the floor that band may reach, and a grid cell sits one step higher. A 16 px multi-glyph item in a scene therefore trains at 0.25–0.6, a 48 px single at 0.7–0.9, and the same row can appear in both kinds of item.
Kanji, and the top edge
Kanji raised the obvious objection. A kana is one stroke path with about 7 cells² of ink at 48 px; 願 or 魔 has 13. If ink moved the band, kanji would want a higher one. So: 24 cold rows in three strata of eight, kana, simple kanji (人 大 口 中 日 手 女 水, the same ink as the kana) and dense kanji (願 構 備 動 聞 精 離 魔, twice the ink), on the same composites, at 0.7–0.9 against 0.8–0.95.
The higher band is a collapse for every stratum. And the rows trained at 0.8–0.95 still have their leverage peak at 0.7: trained above the ceiling, they put what little they have where the model has leverage to give, not where they were trained. "Leverage lands where the row trained" stops at the ceiling's edge. English at 48 px has 0.06 of leverage at σ 0.9, and a band that lives there trains nothing. Nothing above 0.9 for this px, for kana and kanji alike.
Ink doesn't move the band. The dense stratum didn't prefer the higher arm, and across 200 kanji the sign is the opposite of what I expected: more ink per glyph at fixed px puts the leverage peak lower (r −0.44) and makes it smaller. Stroke count is the same variable (r 0.92 with ink) and adds nothing once ink is held. The one structural term that survived is straightness, an orientation-entropy descriptor independent of ink: from the curviest quartile to the straightest the peak rises by about 0.03 σ. Simple kanji sat one σ step above kana at equal ink for that reason, and tolerated the high arm (6 to 7 where kana fell 10 to 3). It is real and it is inside the band, so it changed nothing in the recipe.
What dense kanji did change is the budget. At 48 px in a scene they read 0 of 64 on both arms, and the misses are near-neighbour swaps, 願 drawn as 顔, 聞 as 闘, on top of a dense-kanji texture of the right size and weight. The row had found the neighbourhood and not the identity. That is not a band question; both arms agree. A 14-stroke glyph at 48 px is six latent cells wide. In the shipped pack kanji rows trained on grid cells up to 235 px, and dense rows got 338 steps against 225 for the rest, because that is where the measurement said the cost was: exposure and px, not σ.
The same answer from the gradient
Ten days later I checked the bands with a different ruler, one that looks at what training actually receives rather than at the forward estimate. Take a cold row at step 0 and the true caption. Compute the loss gradient on the row with glyph u drawn in its slot, then again with the slot's glyph swapped to some v, and ask what share of the gradient's energy changed. Call it f. If f is 1 the gradient is all about the glyph; if it is 0 the row would receive the same update whatever was drawn, which is to say it is learning the layout and nothing else.
f sits on a plateau at low σ and falls with σ, earlier for smaller glyphs. Its half point, 0.62 / 0.72 / 0.76 for 15 / 28 / 44 px grid cells, is the ceiling table's upper edge for that px, 0.6 / 0.7 / 0.8. Two rulers that share no code, one on the one-step estimate and one on the backward pass, agree on where the top of the band is. The clearest negative read came from a run that had put every item at 0.75–0.93 by mistake: for 15–28 px glyphs that band gives f ≤ 0.16, a gradient 90% the same whichever glyph is drawn, and the run read zero on every ruler. That is what a wrong band looks like from the gradient's side.
The gradient also says something the ceiling can't. f has no lower edge: below its peak the glyph's share holds while the gradient's size collapses, by 50× between σ 0.6 and 0.2 for a 44 px cell. The lower edge of a band is an exposure edge, not an identity edge. A draw there is a draw the row did not get. I tested that by training three arms on the same 8,200 items at 60 steps per row:
A band from 0 to 0.7 spends about 40% of its draws below σ 0.3, and that is enough to lose almost every single. With a lower edge, the gradient's bands tie the rule's. They do not beat it; they are the same bands widened downward by 0.05–0.1. The cross-check confirms the law and doesn't improve it, which is the outcome I wanted from a cross-check.
What transfers
The rule itself is specific to this model and this task: singles at 0.7–0.9, pieces at 0.5–0.7, floor by px, grid cells one step up, nothing above 0.9. What transfers is the method. Every time you fine-tune a new concept into a frozen diffusion model, a textual-inversion token, a new vocabulary row, a tag the model has never seen, timestep sampling is a hyperparameter, and it has a measurable answer. One forward pass per σ with the concept swapped in and out of the caption tells you where the model will listen to it. The default samplers don't know that: the previous post's uniform schedule spent two thirds of training at σ ≤ 0.6, where a 48 px single glyph has no gradient to give, and the sentence runs spent all of theirs at 0.7–0.9, where a string has none.
Measure first. It costs 90 seconds, and the training runs it would have saved me cost weeks.
The release
The pack those bands trained is out. jp_v1 carries 1,573 trained rows, 163 kana and 1,410 kanji, which cover 96.7% of kanji occurrences in Manga109-s dialogue, up from 92.8% for the preview. It is the default in anima_lora now, under the name anima_cjk_vocab_pack_jp_v1 at sorryhyun/anima-vocab-pack-cjk.
For ComfyUI there is also sorryhyun/anima-jp-extended: base Anima with the rows merged into its embedding table, loaded with the AnimaMergedLoader node, so you type Japanese in the prompt and nothing else changes. The DiT weights are base Anima's, an English prompt tokenizes exactly as before, and any Anima LoRA stacks on it as is. Same prompt, same seeds, with and without the rows:
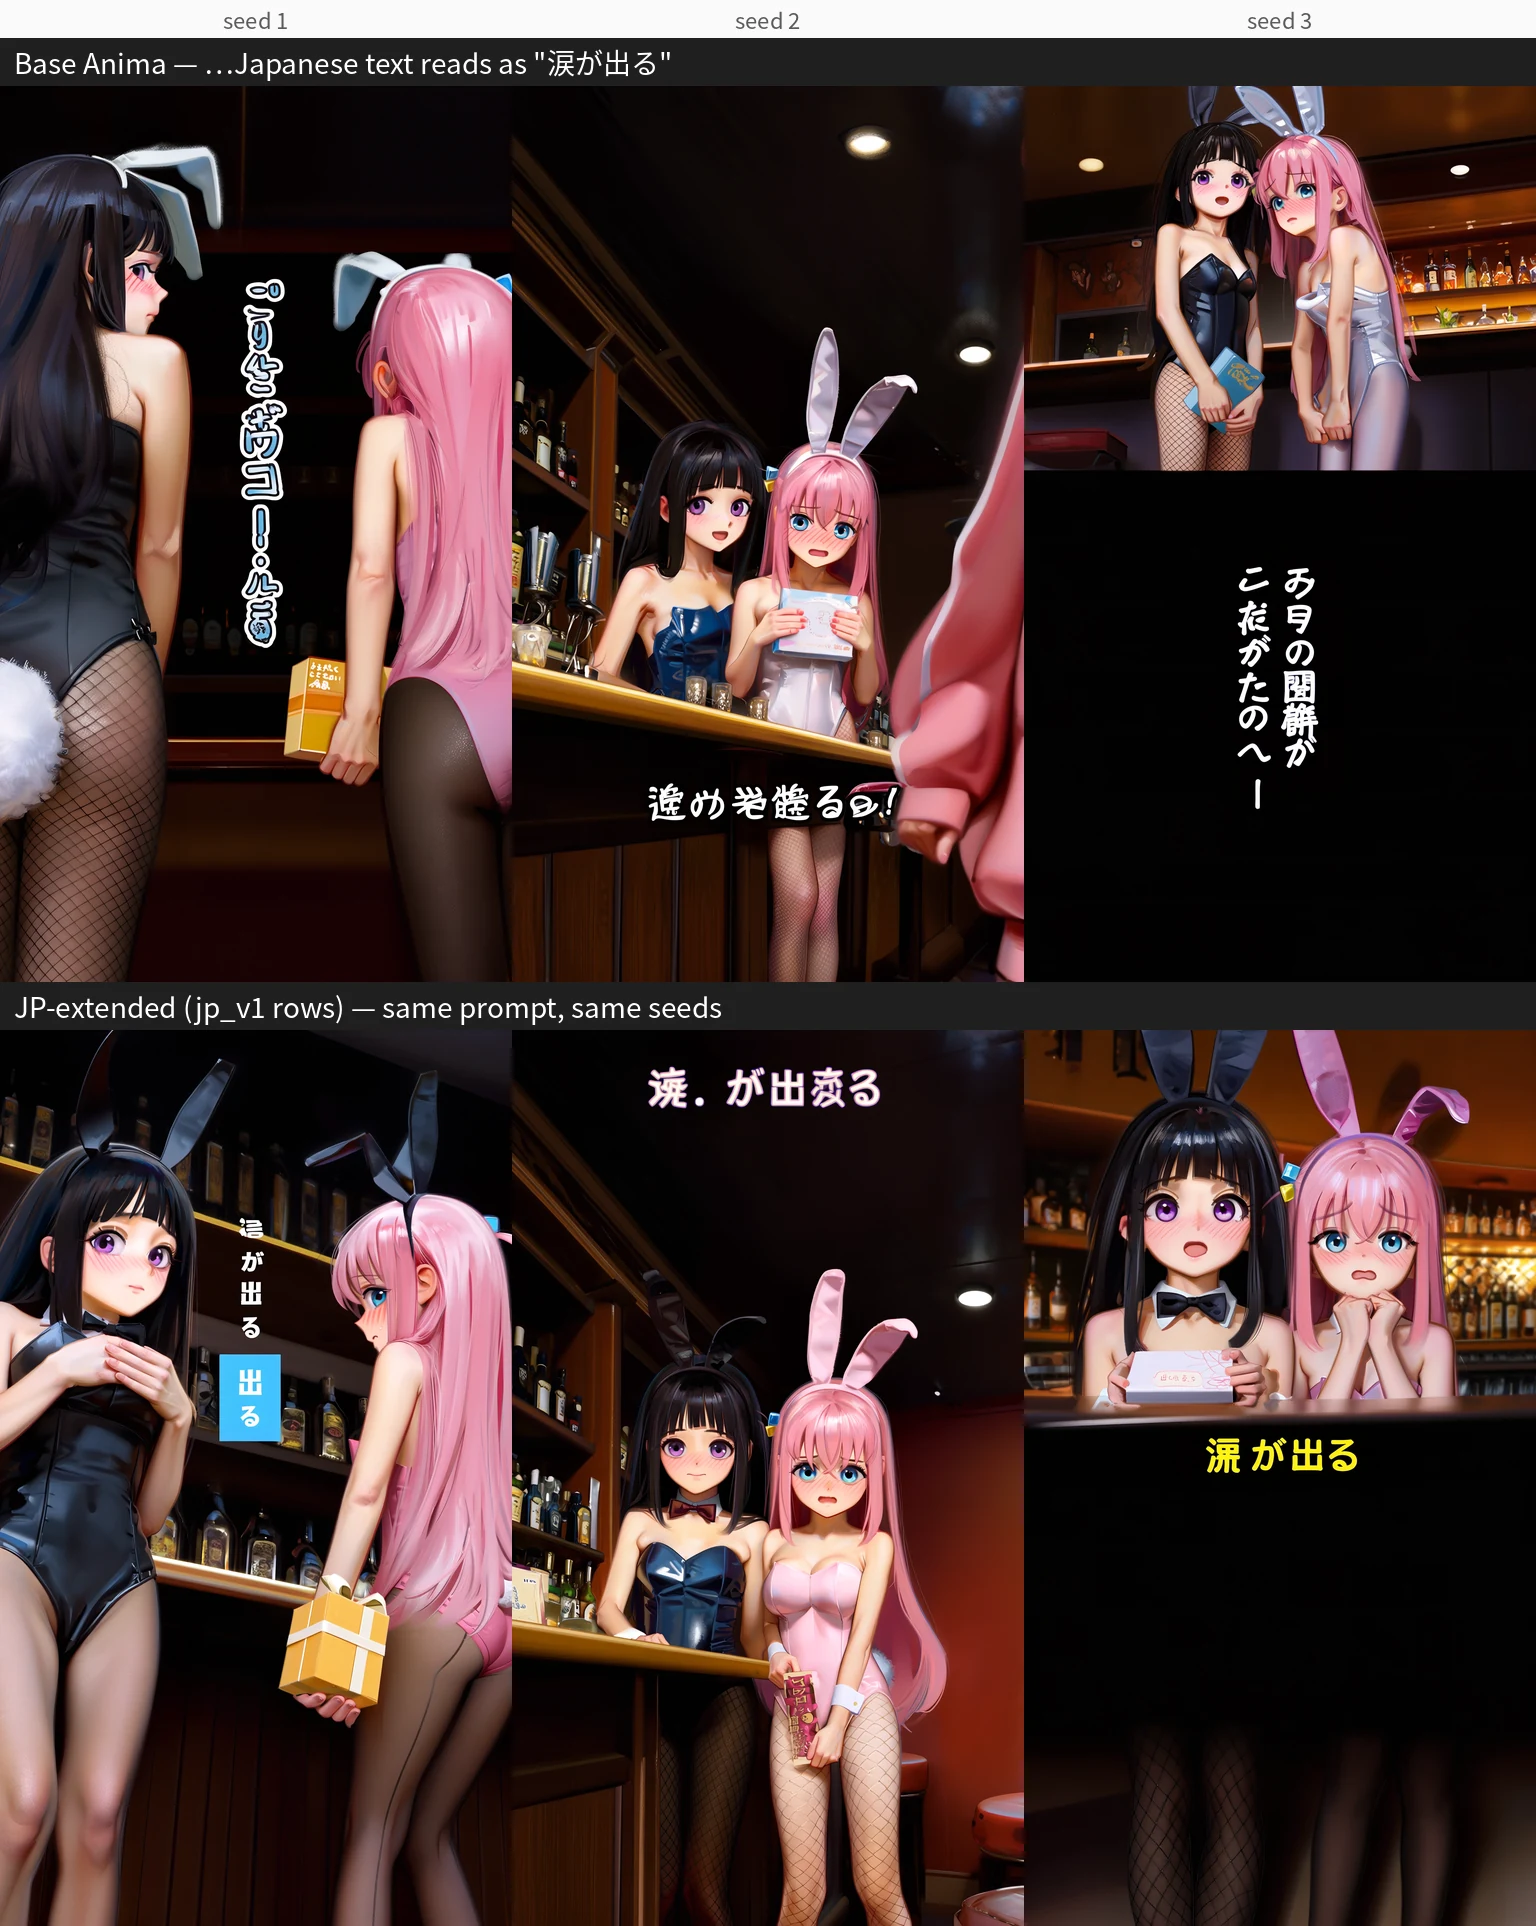
The rows live in the text-side embedding table, not in the DiT blocks, so a derivative that keeps base Anima's table can take the pack directly. The official anima-turbo-v1.1 is one: its embedding table is base's bit for bit, and with the pack loaded it draws the string at 8 steps, loosely.
It is not finished. Lines of ten or more glyphs are rarely letter-perfect, horizontal text is 7% of the training items and unmeasured, and the rows can't draw text more cleanly than Anima itself does. The training recipe also has a second term the bands alone don't explain, a loss that keeps the page from turning into a column of text when the line gets long. That one deserves its own post.